Add a pipeline
To add a pipeline, in Registry, click the Pipelines tile, then click + Add pipeline. Adding a pipeline has three steps: Definition, Inputs, and Image. After Create, DataRobot starts image construction in the background and opens the pipeline.

For @dr.task, @dr.pipeline, inputs, images, and Draft vs Locked, see Pipelines overview.
Define the pipeline
The Definition step names the pipeline and supplies the Python logic.
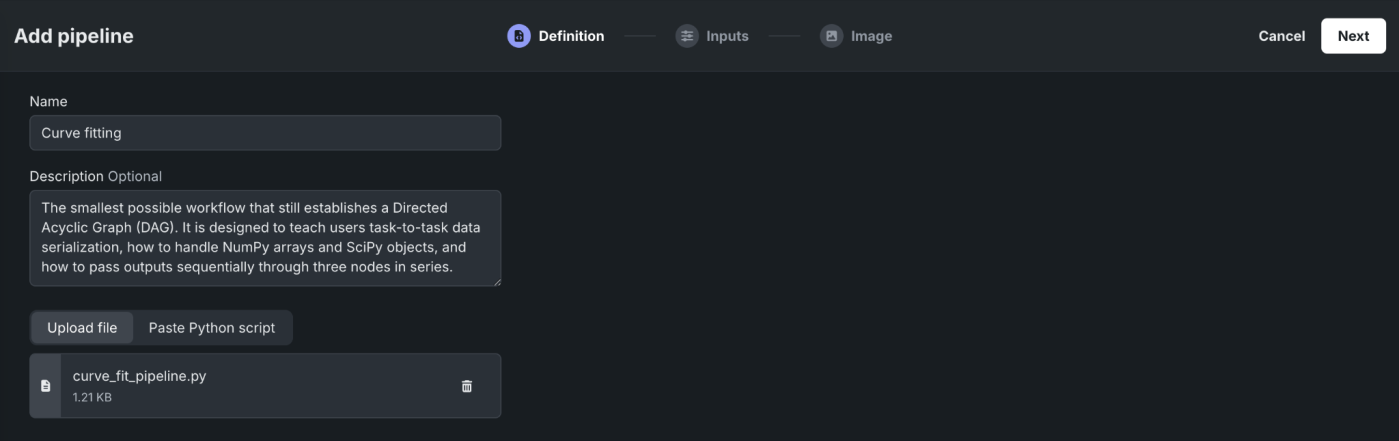
- Enter a Name and, optionally, a Description.
- Click Upload file or Paste Python script to provide the pipeline source. The file must include
@dr.taskand@dr.pipelinefunctions. - Click Next.
The pipeline is saved as a Draft after this step. Continue through the remaining steps, or close the page and return later to finish configuration.
Define pipeline inputs
The Inputs step does not change the Python file. DataRobot reads the @dr.pipeline function signature and fills a YAML editor with those parameter names. The values are injected when the pipeline runs, so the same pipeline can run many times with different input sets.
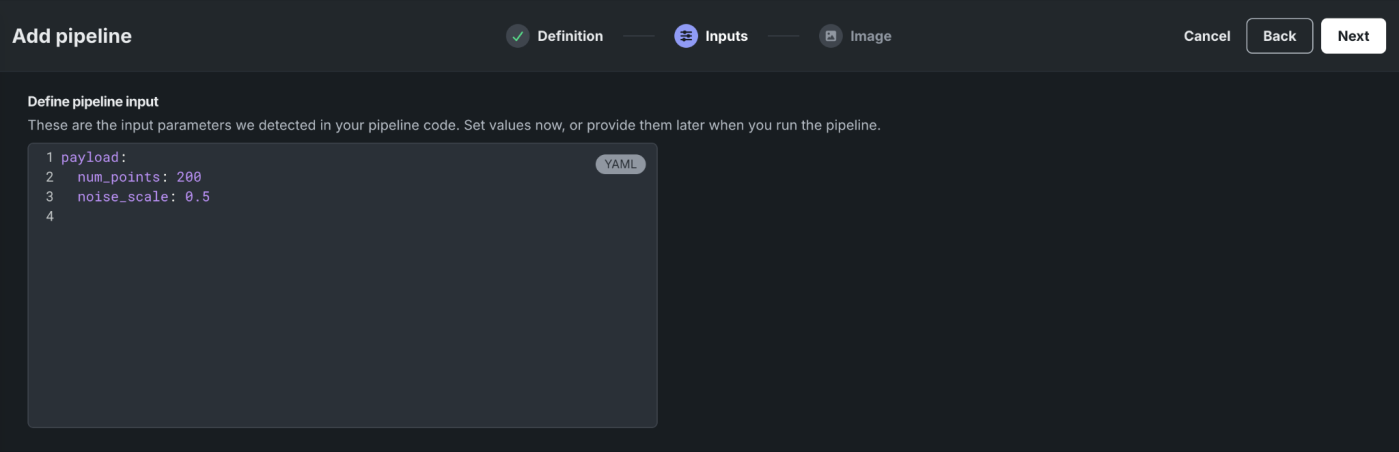
Set values now, or leave placeholders (for example, null) and provide them later in the Run pipeline dialog. Click Next to continue, or Back to return to Definition.
Define the pipeline image
The Image step selects the container every task runs in. Choose an existing image or create a new one.
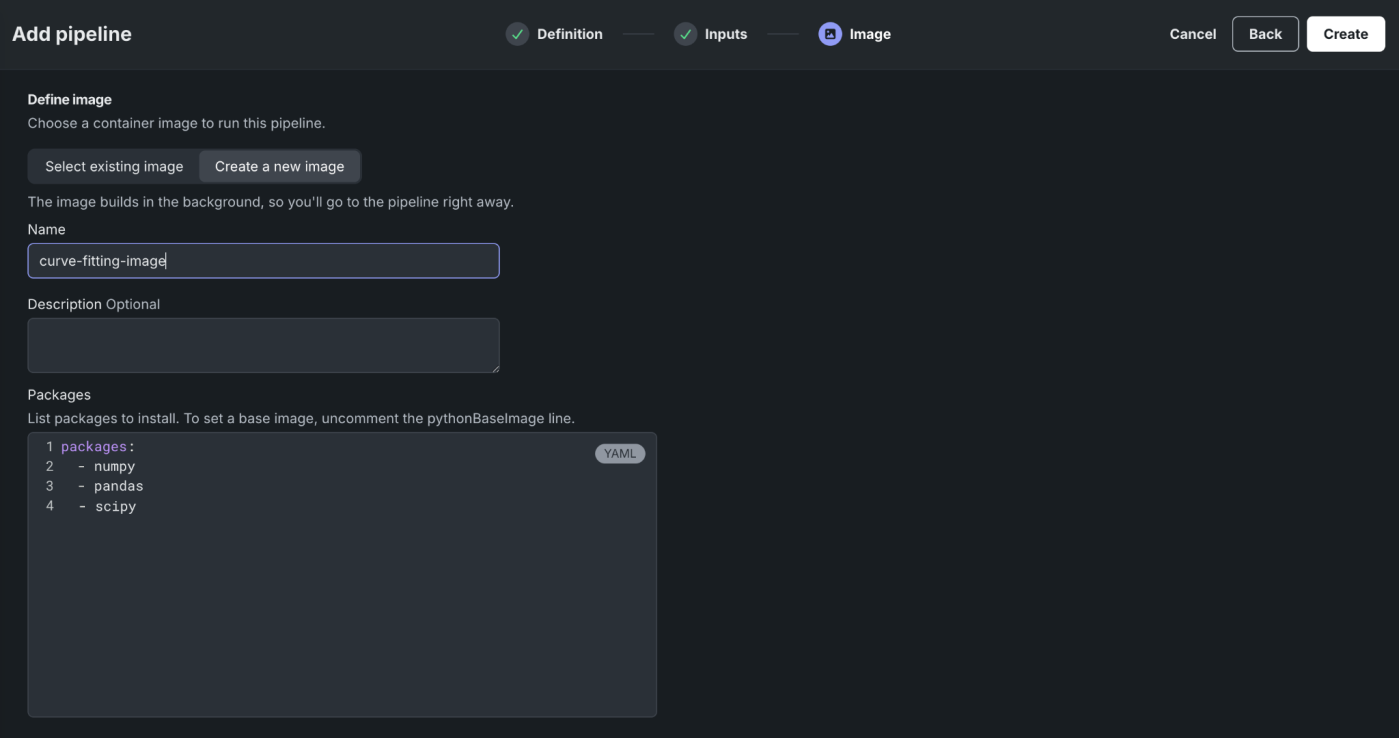
To reuse an image, click Select existing image and choose it from the list.
To create an image, click Create a new image and follow the instructions in Create an image.
The image builds in the background and the pipeline opens immediately. A run cannot start until Status is Ready. Track the build on the Images tab.
Next steps
After adding a pipeline, inspect the DAG, run it, or check the image build.
- View and manage pipelines: Open the pipeline to review the workflow DAG, details, and runs.
- Run and schedule pipelines: Start a run or lock the pipeline for a recurring schedule.
- Manage pipeline images: Review build status or reuse an image across pipelines.