Tutorial: Build a pipeline
Turn a Python file into a scheduled, monitored, multi-task workflow. Decorate functions with @dr.task, connect them inside a @dr.pipeline, then upload and run the pipeline. DataRobot runs each task in its own container, executes independent branches in parallel, and records status, logs, and results for the run.
From Registry, click the Pipelines tile and then Add pipeline.
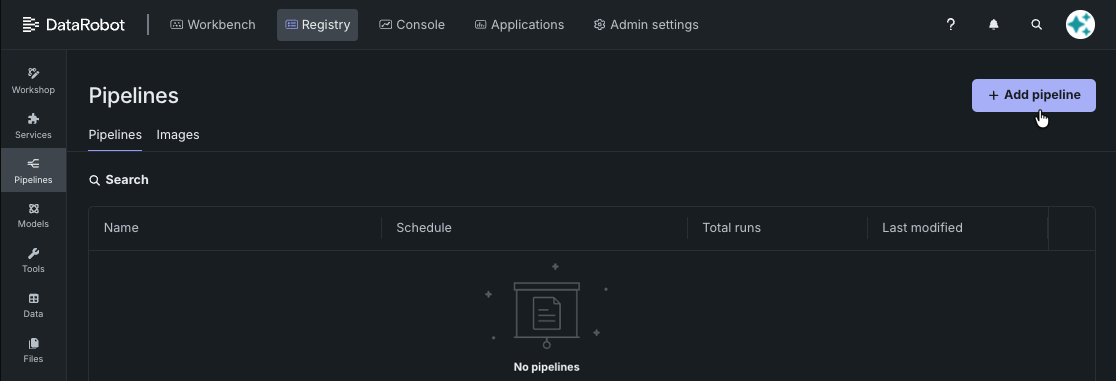
The pipeline building process uses three steps: Definition, Inputs, and Image.

Add the Python script
On the Add pipeline page—the Definition step—upload a file or paste a Python script. For this tutorial, paste the following file, classifier.py, which is the pipeline. It consists of four tasks—the prepare_data and prepare_labels tasks run in parallel, and the subsequent tasks initiate training and predictions.
import datarobot as dr
from sklearn.tree import DecisionTreeClassifier

@dr.task
def prepare_data():
    return [[140, 1], [130, 1], [150, 0], [170, 0]]

@dr.task
def prepare_labels():
    return [0, 0, 1, 1]

@dr.task
def train_classifier(features, labels):
    model = DecisionTreeClassifier()
    model.fit(features, labels)
    return model

@dr.task
def make_prediction(model, x_new):
    prediction = model.predict(x_new)
    print(f"model prediction is {prediction}")
    return prediction.tolist()

@dr.pipeline(resource_bundle="cpu.small")
def classifier(x_new):
    features = prepare_data()
    labels = prepare_labels()
    model = train_classifier(features, labels)
    return make_prediction(model, x_new)
Click Next.
Add pipeline inputs
After the script is in place, click Next to open the Inputs step. This step does not change the Python file. It stores the parameter values DataRobot injects into the @dr.pipeline function when the pipeline runs. The same pipeline can then run many times with different input sets. In this tutorial, the input is classifier(x_new), instructing the feature row to score after training.
Define the input parameters:
payload:
  x_new: [[160, 0]]
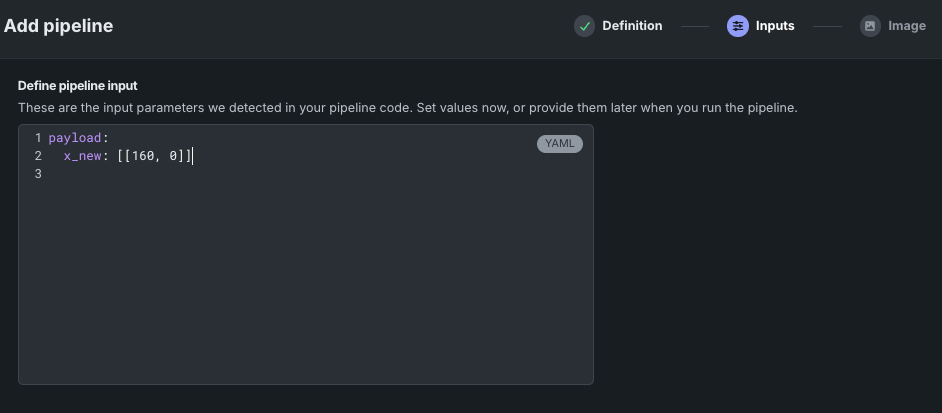
Click Next to set the image.
Add an image
The image is the container every task runs in. Each package in the YAML is pip-installed into that image.
On the Image step, click Create a new image (or Select existing image to reuse one). Enter a Name, for example quickstart-image, and optionally a description.
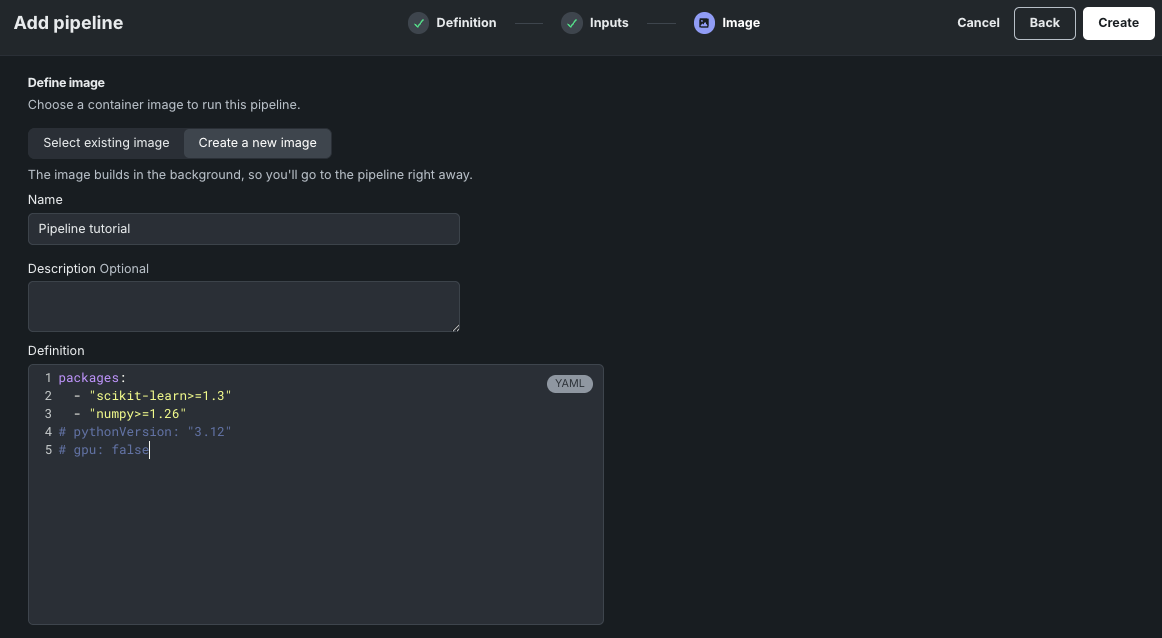
The Definition editor already lists sample packages. This tutorial uses scikit-learn, so replace the list with:
packages:
  - "scikit-learn>=1.3"
  - "numpy>=1.26"
# pythonVersion: "3.12"
# gpu: false
Leave pythonVersion and gpu commented unless a different Python version or a GPU image is required.
Click Create. The image builds in the background and the pipeline opens immediately. A run cannot start until Status is Ready; check build status on the Images tab.
View the pipeline
Once created, the Pipelines home page opens.
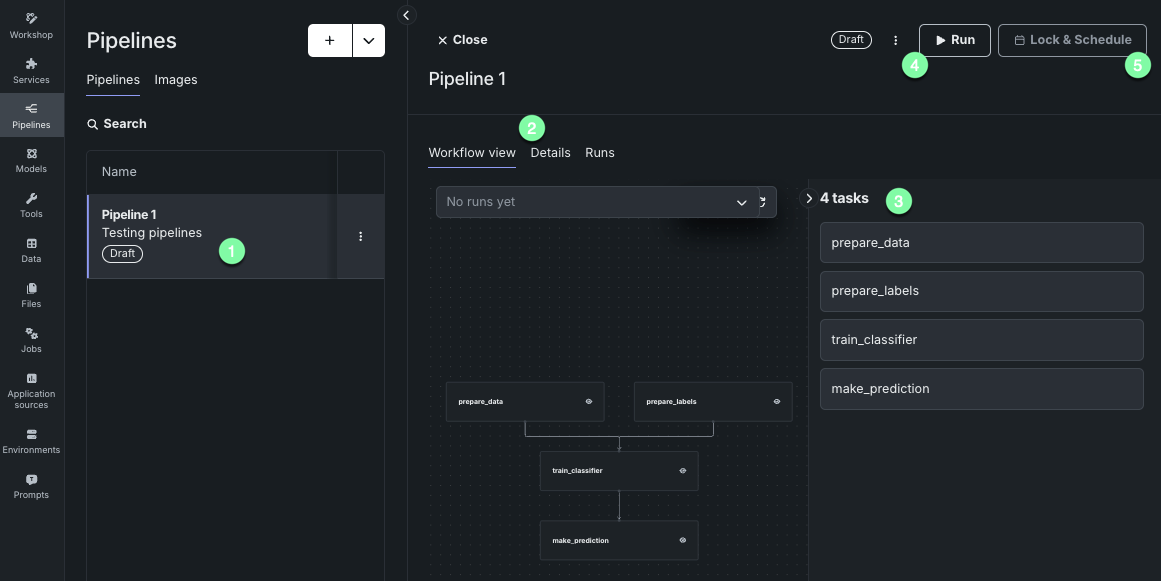
- Click a pipeline to select it (1). By default, the DAG displays.
- Click through the tabs for pipeline detail. Until the pipeline has been run, the Runs tab is empty (2).
- Click a task name to expand it and view the code (3).
- Click Run to run the pipeline (4). When the run completes, the Runs tab populates.
- After a run, lock and schedule the pipeline (5).
Next steps
To build a pipeline, add it, then inspect the DAG, run it, or check the image build.
- Add a pipeline: Create a pipeline from Python source, inputs, and an image.
- View and manage pipelines: Open the pipeline to review the workflow DAG, details, and runs.
- Run and schedule pipelines: Start a run or lock the pipeline for a recurring schedule.
- Manage pipeline images: Review build status or reuse an image across pipelines.